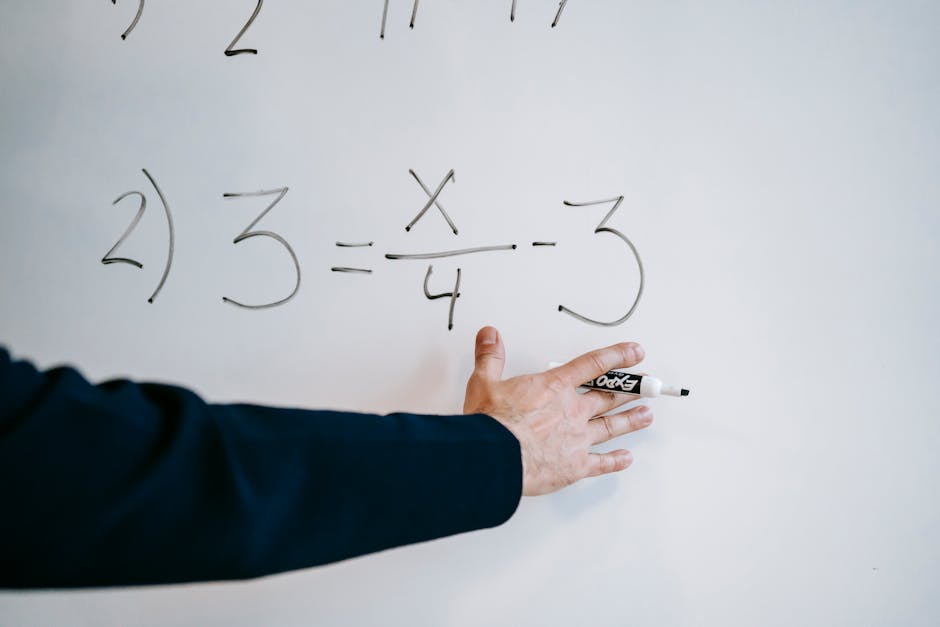
Your daughter’s math homework comes back with a red X. The answer is wrong. But she does not know why it is wrong, and the X does not tell her. She gets a correct answer on the next problem through luck. The underlying misunderstanding goes uncorrected.
Now imagine the homework comes back with the same red X, but this time the teacher has written in the margin: “You carried the 4 instead of the 7 in the second column. Go back to column two.” The mistake is identified. The path to correction is visible.
AI explanation is the teacher’s margin note. The system does not just produce an answer. It identifies which parts of the input drove which parts of the output, and it makes that visible to the human reviewer.
Why Explanations Matter
A model that produces answers without explanations gives you no handle on when it is wrong. You either trust it or you do not. Explanations give you something to evaluate. You can read the explanation and ask: does this reasoning hold? Is this the part of the input that actually supports this conclusion?
This matters most in high-stakes domains. A model that recommends a drug interaction without explaining why is harder to trust than one that says “I flagged this because the patient record shows simvastatin and you specified a high-fat meal, and simvastatin is contraindicated with high-fat meals.” The explanation lets the clinician evaluate the reasoning rather than simply accepting the output.
The explanation also enables correction. If the model explains its reasoning and the reasoning is based on a misread input, you can correct the input and rerun. If the model gives only an answer, you cannot distinguish a wrong answer caused by a misread from a wrong answer caused by flawed reasoning.
In lower-stakes domains, explanations matter less. If you are asking for a restaurant recommendation, you do not need to audit the model’s reasoning. A bad recommendation is an inconvenience, not a safety issue. The overhead of explanation is not worth it.
What Explanations Explain
Not all explanations are equally useful. An explanation that says “I answered this way because of relevant context in the input” is better than nothing but does not give you much to evaluate. An explanation that names the specific part of the input that drove the specific part of the output is much more useful.
The technical term for this is attribution. The system attributes parts of its output to parts of its input. Good attribution means you can trace the chain from input to output and verify each step.
There are different levels of attribution. Token-level attribution shows which input tokens most influenced each output token. Sentence-level attribution shows which input sentences contributed to which output sentences. Document-level attribution shows which retrieved documents most influenced the answer.
The level you need depends on the task. For a task where the model is drawing from a specific retrieved document, document-level attribution may be sufficient. For a task where the model is reasoning across multiple pieces of a long input, token-level attribution may be necessary to pinpoint the problematic reasoning.
How Explanations Are Generated
Explanations are not free. Computing attributions requires additional passes through the model or additional architecture specifically designed for explanation.
One approach is to generate the explanation as part of the output: ask the model to explain its reasoning and include that explanation in the response. This is cheap but unreliable: the model may generate explanations that sound plausible but do not accurately describe the actual computation.
Another approach is to use a separate attribution model that is trained to predict which inputs drive which outputs. This is more reliable but adds a separate model to run.
A third approach is to use architectural features that make attribution tractable: systems that track attention weights, systems that maintain intermediate reasoning state. These make attribution available as a byproduct of inference rather than an additional cost.
The explanation generation overhead is worth considering in latency-sensitive applications. If you need answers in under a second, explanation generation may push you over your latency budget. You may need to choose between explanations and speed.
Explanations and Trust
Explanations can create a false sense of security. A model that explains its reasoning in confident, fluent prose may be producing explanations that sound right but are wrong. Humans are susceptible to trusting fluent, confident explanations even when the explanations are not accurate.
This is the inverse of the problem without explanations: you had no handle on errors before, and now you have handles that may themselves be misleading.
Good explanations need to be calibrated. The system should be able to express uncertainty about its reasoning, not just state reasoning confidently regardless of confidence level. An explanation that says “I am uncertain about X, but confident about Y” is more trustworthy than one that states everything with equal confidence.
Explanations for Compliance
In regulated domains, explanations may not be optional. If you are making lending decisions, you may be legally required to explain why. If you are providing medical information, you may be required to cite sources. Explanations are not just good practice; they may be legal requirements.
The regulatory requirements shape what counts as an acceptable explanation. A vague statement that the model “considered all relevant factors” is unlikely to satisfy a regulator. A specific citation of which data points drove which decisions is more likely to pass scrutiny.
Building explanation capabilities into systems that will operate in regulated domains is not optional. It is part of the compliance architecture.
Real-World Scenario: The Loan Denial
A bank uses an AI system to assist in loan decisions. The system denies an application and provides this explanation: “The application was denied because the debt-to-income ratio exceeds our threshold and the applicant has a limited credit history.” The explanation cites specific numbers: debt-to-income of 47% versus the threshold of 40%, and credit history of 2 years versus the required 3 years.
The loan officer reviews the explanation and verifies the numbers against the application. The explanation is accurate. The officer sustains the denial and communicates it to the applicant with specific, verifiable reasons.
Without this explanation, the officer would have had to reverse-engineer the decision from the application’s raw data, which is time-consuming and error-prone. The explanation makes the decision auditable and the denial communicable.
Real-World Scenario: The Hiring Tool
A company uses an AI tool to screen resumes. The tool flags a resume as “unusual” and suggests human review. The explanation: “This resume has significant keyword gaps compared to successful resumes for this role. Specifically, it does not mention [technical skill X] or [technical skill Y], which appear in 80% of successful resumes.”
The hiring manager reads the explanation and decides the candidate is still worth interviewing because the resume shows adjacent experience that the keyword analysis missed. The explanation helped the manager identify a potential false negative without requiring the manager to understand the underlying screening model.
The explanation here is not about why the candidate was rejected, but about why the resume warranted extra scrutiny. The human makes the final call, informed by the model’s analysis.
Real-World Scenario: The Medical Diagnosis
A diagnostic system explains its reasoning: “The patient presentation is consistent with three possible conditions: A, B, and C. Condition A is most likely because the patient has symptom X and lacks symptom Y. Condition B is less likely because while the patient has symptom Z, they lack the typical presentation. Condition C is unlikely based on the patient’s demographics and the typical age distribution.”
The physician reviews the explanation. They note that the patient actually does have symptom Y, which was missing from the initial record. They correct the record and rerun the analysis. The revised explanation changes the ranking of conditions.
The explanation did not just help the physician trust or verify the output. It helped identify missing data. The model’s reasoning was sound given its inputs; the inputs were incomplete.
The Calibration Problem
Explanations that do not convey uncertainty are misleading. A model that states “the debt-to-income ratio is 47%” with the same confidence as “the sky is blue” creates false certainty about numbers that might be wrong.
Good explanation systems express confidence calibrated to the actual reliability of the computation. The model should be able to say “I am highly confident that the debt-to-income ratio is above 40%, but less confident about the exact figure because some income sources were unclear in the application.”
This calibration is hard to produce reliably. Models are often overconfident in wrong answers. Calibrating explanations to match actual accuracy requires testing and validation that most systems skip.
Explanations and User Trust
Explanations affect user trust in complex ways. An explanation that is accurate but incomplete may reduce trust compared to no explanation, because the user acts on a partial understanding that proves wrong. An explanation that conveys uncertainty may reduce trust compared to a confident explanation, even if the uncertain explanation is more accurate.
This is the trust calibration problem. Users form mental models of the system’s reliability. Explanations shape those models. If the model is more reliable than the user’s mental model, the user under-trusts and underuses the system. If the model is less reliable, the user over-trusts and overuses it.
Effective explanations calibrate user trust to actual system reliability. This means being honest about uncertainty while also being confident when confidence is warranted. The goal is not maximum trust, but calibrated trust.
Explanations vs Interpretability
There is a distinction between explanations and interpretability that is often conflated.
Interpretability refers to the ability to understand how a model works internally. A linear model is interpretable: you can see exactly how each input feature contributes to the output. A deep neural network is not interpretable in the same way: the computation is distributed across millions of parameters in ways that are not human-understandable.
Explanations refer to the outputs a system produces about its reasoning. An explanation can be post-hoc: generated after the fact to justify a decision. Interpretability is structural: it describes the model’s actual computation.
Post-hoc explanations of an uninterpretable model may be misleading. The model did not actually reason in the way the explanation describes. The explanation is a plausible reconstruction, not a description of the actual computation.
This does not mean post-hoc explanations are useless. They are useful if they are accurate enough to be actionable. But you should not mistake a confident explanation for transparency into the model’s actual computation.
Explanations in Multi-Agent Systems
When multiple agents contribute to an output, explaining that output becomes more complex. Which agent’s reasoning should be explained? The agent that produced the final output? The agent that contributed the key intermediate result? All of them?
A medical diagnostic system might have one agent that retrieves relevant literature, another that applies diagnostic criteria, and a third that generates the final explanation. The final explanation might reference literature that the retrieval agent found, criteria that the diagnostic agent applied, and formatting that the generation agent chose.
Attributing each part of the explanation to the correct agent requires instrumentation that most systems lack. Without this attribution, the explanation is a single generated text that may conflate contributions from different agents.
The Explanation Complexity Trade-off
Explanations have complexity costs. More detailed explanations require more tokens, more generation time, and more processing to compute attributions. They also require more effort from the user to read and evaluate.
Simple explanations are cheaper to generate and easier to read. They may also be more actionable: a user can quickly scan a simple explanation and decide whether to trust it or investigate further.
Complex explanations provide more detail but at the cost of cognitive load. A user who receives a ten-page explanation may not read it carefully. The explanation’s value is reduced if the reviewer does not engage with it.
The right level of explanation complexity depends on the stakes and the reviewer’s available attention. High-stakes decisions warrant detailed explanations. Routine decisions warrant simple explanations.
Explanations and Debugging
Explanations are most valuable when something goes wrong. When an output is clearly wrong, an explanation tells you where to look for the error.
The error might be in the input: the model misread a number, misidentified an entity, or used stale context. The explanation points to the problematic input.
The error might be in the reasoning: the model applied the wrong rule, drew the wrong inference, or made an arithmetic mistake. The explanation points to the step where the reasoning went off track.
The error might be in the output: the model generated text that does not match its reasoning, or the reasoning was sound but the output was poorly expressed. Different explanation types catch these different failure modes.
Without explanations, debugging is a guessing game. You know the output is wrong. You do not know why. Explanations narrow the search space.
Decision Rules
Use explanations when:
- The output will be reviewed by a human before being acted on
- The domain has high stakes where errors are costly
- You need to build trust by making reasoning visible
- Regulatory or audit requirements call for explainable decisions
- You have verified that explanations are accurate, not just fluent
- You need to identify where errors originate for debugging or correction
- You are building multi-agent systems where attribution across agents matters
- You need to calibrate user trust to actual system reliability
Do not use explanations when:
- The output is low-stakes and speed matters more than auditability
- The explanation generation overhead is disproportionate to the value
- The explanations themselves would reveal sensitive information
- You cannot verify that explanations are accurate
- The system is used in a mode where users want answers, not analysis
- The explanation generation would make the system prohibitively slow
- The cognitive load of explanations would exceed their value for the review task
The teacher’s margin note turns a wrong answer into a learning opportunity. Without it, the student corrects the symptom, not the cause. With it, the student can see exactly where the reasoning went wrong and fix it at the source.